The stack teams use
Python, SQL, PySpark and cloud platforms, taught in a logical order.
A structured, month-by-month path from Python and SQL to PySpark, ETL and cloud data engineering on AWS and Azure — finished with real projects and complete career preparation.
This program teaches you to move, clean, transform and serve data at scale. You start with the languages of data — Python and SQL — then learn distributed processing with PySpark, build ETL pipelines, and deploy them on the cloud.
The final two months are spent on projects and career preparation, so you finish with work you can show and the confidence to talk about it.
Every company that uses analytics or AI needs someone to collect, clean and deliver the data first. That person is a data engineer.
Python, SQL, PySpark and cloud platforms, taught in a logical order.
Always know what you are learning and why, from basics to projects.
The last two months focus on projects, resume and mock interviews.
Live classes plus one-to-one mentorship from experienced practitioners.
The job title can sound technical. These are the everyday tasks behind it, with simple examples.
Create automatic routes that carry data from where it starts to where it is needed, cleaning it on the way.
For exampleMoving daily sales from every shop into one tidy database.
Store years of data in one organised place so analysts and models can use it quickly.
For exampleOne place where orders, customers and payments can be analysed together.
Handle data that arrives constantly, second by second, instead of once a day.
For exampleTracking live website activity as it happens.
Use services on AWS and Azure to store and process data without buying servers.
For exampleRunning a nightly job in the cloud that refreshes company reports.
Check that the data is complete and correct before anyone depends on it.
For exampleCatching duplicate or missing records before they reach a report.
Analysts and machine learning teams rely on ready, trusted data to do their work.
For exampleA sales dashboard that is always up to date because the pipeline feeds it.
The path starts from the basics, so you can join from different places. Here is how it helps each kind of learner.
You want to start building job-ready skills before you graduate.
You are looking for a clear route into your first data role.
You work in support, testing or development and want to move into data.
You are new to technology and want a fresh start.
The detailed roadmap covers every month of the program: goals, topics, hands-on work and the final real-time project. Share your details and download it as a PDF.
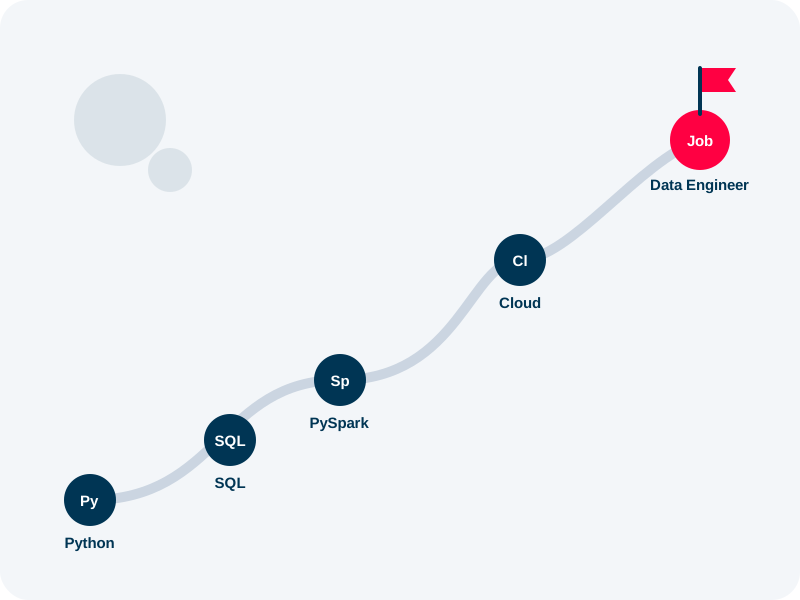
Follow a structured route from Python and SQL through PySpark and cloud, then projects, resume work and interview preparation.
Market observations are taken from the DataIQ Labs brochure.
Download the complete DataIQ Labs brochure, including the roadmap, program details and contact information.
of data engineering professionals report there is a shortage in the field.
Demand exceeds supply, especially for experienced cloud-native engineers. Entry level pay is Rs 10-15 LPA, the median in internet and e-commerce is Rs 28.5 LPA, and in tier-1 cities Delhi NCR is Rs 19.3 L and Bengaluru Rs 19 L. Freshers can enter, but hands-on projects with cloud and data pipeline skills are key to standing out.
Huge opportunities in data engineering. Companies compete for skilled mid and senior engineers. Upskilling and practical experience are the fastest ways for freshers to bridge the gap.
Figures as published in the DataIQ Labs brochure.
Share a few details and our team will call you to discuss batches, fees and whether the program fits your background.